Outside the US and China, the world is building last year’s AI
Countries outside the US and China want AI labs of their own, an idea often called sovereign AI. France has Mistral, Canada has Cohere, the UAE has the government-funded Technology Innovation Institute, South Korea has half a dozen labs building Korean models, and India’s national AI mission supplies the compute for Sarvam AI. Village’s LLM Atlas puts 857 models on one capability scale estimated from hundreds of public benchmarks, which lets us measure how far behind each of them is. Since 2024, the best of them have trailed the US by nearly a year.
Everyone else trails by nearly a year
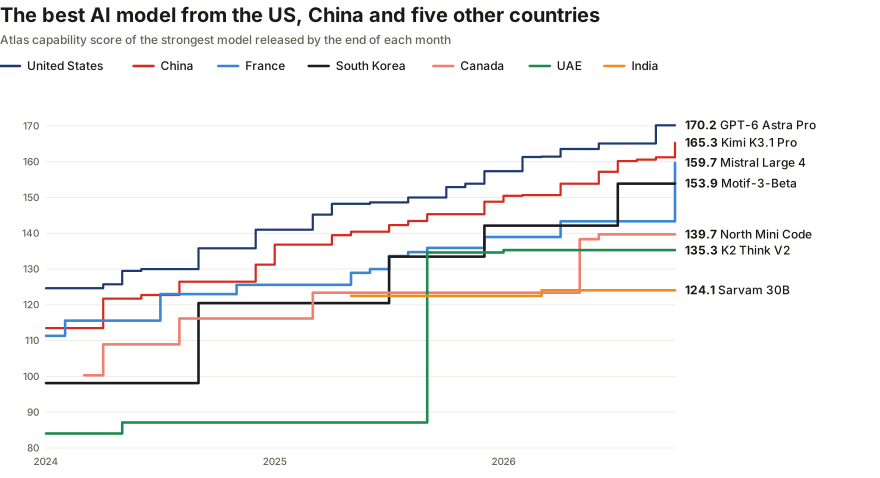
- About 10 months behind the US. Since 2024, each new best model from outside the US and China has arrived a median of 9.9 months after a US model reached the same score, and never less than 7.3 months after.
- Nearly twice China’s gap. New Chinese records have arrived a median of 5.2 months behind.
- They release far fewer models. Labs outside the two countries released about 20 of the models Atlas ranks from 2026, against 113 from the US and 79 from China.
Sovereign labs are not falling further behind, but they are not catching up either. They have stayed in a band about a year back, while China runs about half that distance behind the US.
Country by country
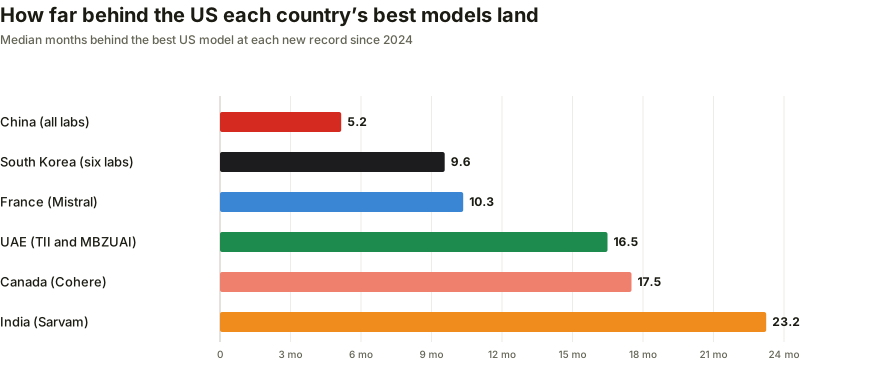
- South Korea and Mistral run closest to the US. Their new records have landed about 10 months behind.
- India is furthest behind. Sarvam AI’s best model, Sarvam 30B from March, scores where US models were 28 months earlier.
Those medians cover two years in which most of these efforts changed course, and since then their gaps have moved in opposite directions.
Their strategies are diverging
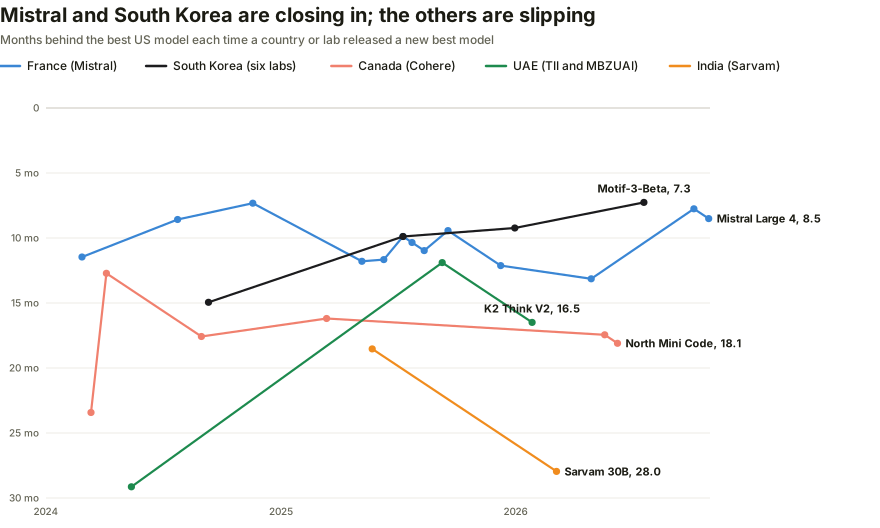
- Mistral went back to open-weight flagships. After a 2025 in which its best models were closed, it released Mistral Large 4’s weights in October and pitched it as Europe’s answer to China’s open models. That cut its gap to about 8 months.
- South Korea is closing in. A government program funds rival labs to build national models and narrows the field each round, and Korea’s gap has roughly halved since 2024. Its best model, Motif-3-Beta, came from a team the program dropped in August despite the top benchmark score.
- Cohere bet on enterprise software. It now sells North, an agent platform that also runs other companies’ models, and in April agreed to buy Germany’s Aleph Alpha. Its own models have slipped to about 18 months behind.
- The UAE is building compute more than models. Its flagship project is Stargate UAE, a data-center campus built with OpenAI. MBZUAI’s K2 Think V2, the country’s best model, sits more than 16 months behind.
- India moved from fine-tuning to training its own. Sarvam’s first model adapted Mistral Small; Sarvam 30B and 105B, trained from scratch on government-funded GPUs, land further behind.
The two efforts closing in are still training large general-purpose models of their own. The others have put more into platforms, data centers or national-language models, which a general capability score rewards less.
How we built this
This study uses Village’s LLM Atlas, which estimates one capability score per model from public benchmark results with a Bayesian item-response model, described in its methodology. Labs are assigned to the country of their headquarters. Months behind measures how long before a model’s release a US model first reached the same score, at each new best model for a country or lab since 2024; Atlas covers few models from before 2023, so early-2024 gaps rest on thinner comparisons. Cohere’s Command R, from March 2024, is 23 months behind only because DeepMind’s Chinchilla reached its score in 2022. The scores are from October 31, 2026; Atlas updates as new results arrive.
We leave out two models built on other labs’ work that would otherwise lead everyone outside the US and China: Sakana AI’s Fugu Ultra, an orchestrator that routes questions through other labs’ models, and Mind Lab’s Macaron-V1-Venti, which adds fine-tuned specialists to Zhipu’s Chinese GLM-5.2. Restricting to models scored on at least 10 benchmark families gives the same order and similar gaps, though it drops Sarvam, none of whose models has that many. Atlas’s benchmarks are mostly in English, which may understate models built for Korean, Arabic, Indian or other languages. India’s figure rests on two Sarvam models. Mistral Large 4’s weights came out on October 29.