Closed AI models now dominate the price-performance frontier
For any budget, there is a most capable AI model you can run for that price. Together, those best buys make up the price-performance frontier. Village’s LLM Atlas estimates both halves of it: a capability score for each model and reasoning setting, and what each one costs to run a task. Right now, almost every point on the frontier is a closed model.
Closed models hold almost every budget
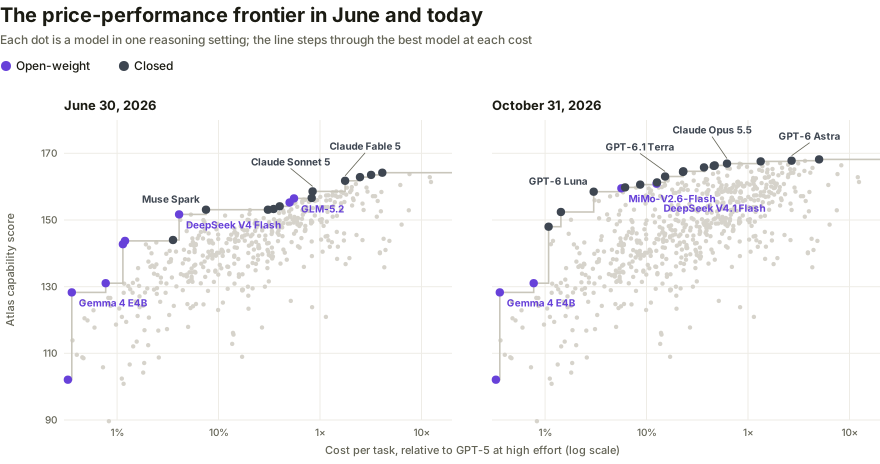
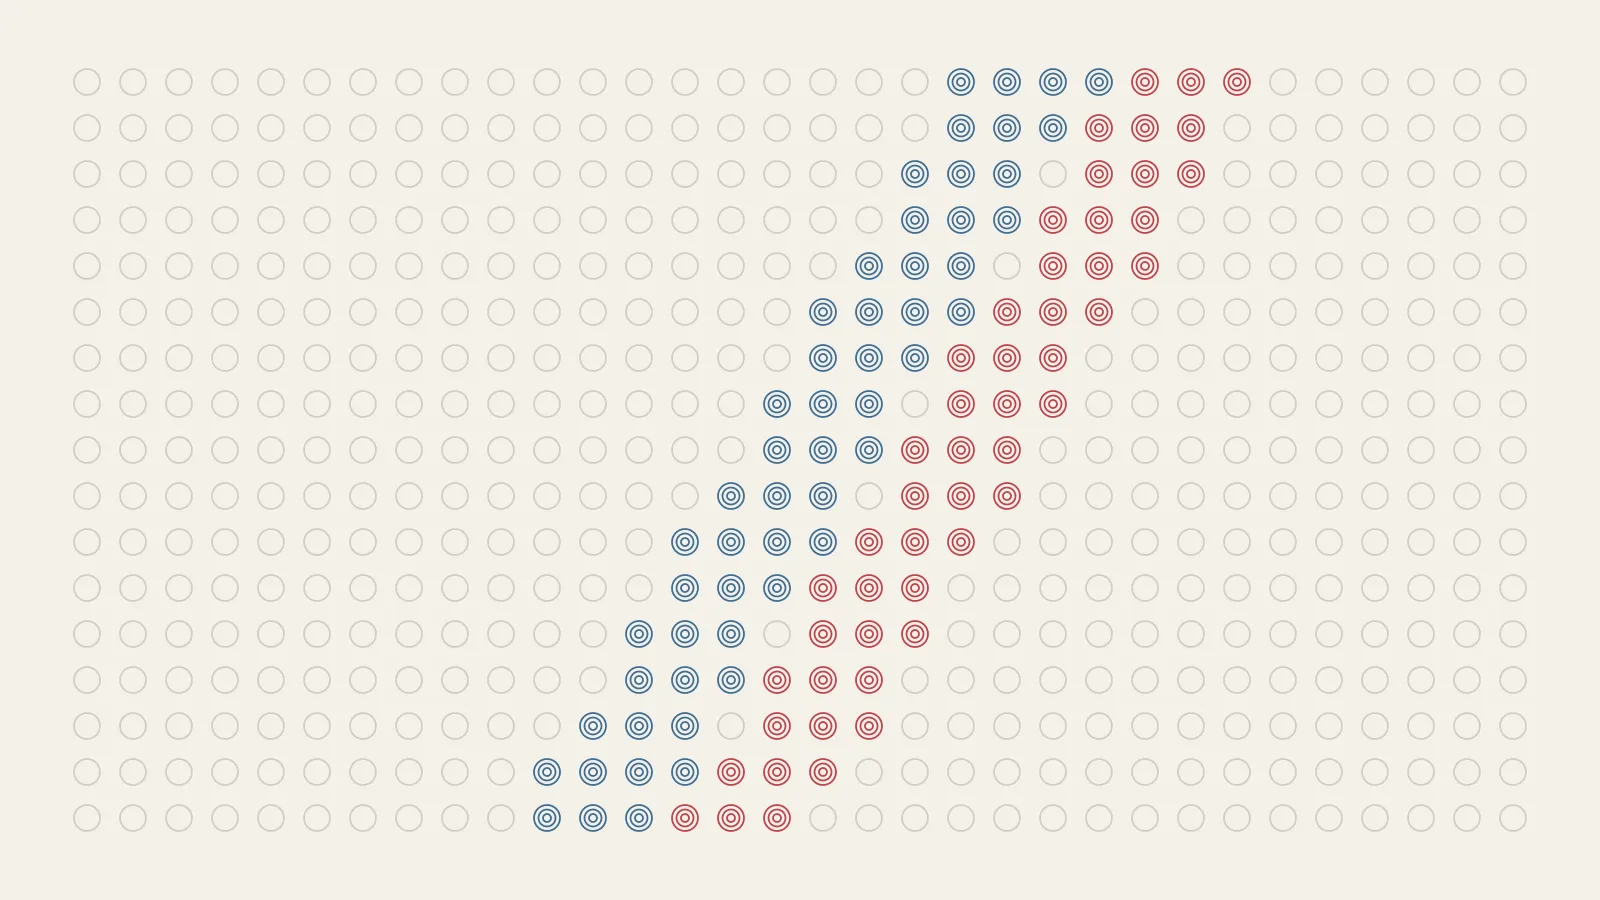
- An open-weight model is the best buy at 3% of budgets. Nearly all of those are at the cheap end, held by Google’s Gemma 4 E4B and Xiaomi’s MiMo-V2.6-Flash.
- In June, it was 41%. DeepSeek V4 Flash alone was the best buy across nearly a third of budgets, with Zhipu’s GLM-5.2 just above it.
- Two OpenAI releases took most of that back. GPT-6 Luna in September and GPT-6.1 Terra in October now cover the budgets open models used to win, alongside Anthropic’s Claude Haiku 5.5.
Open models have led on value before
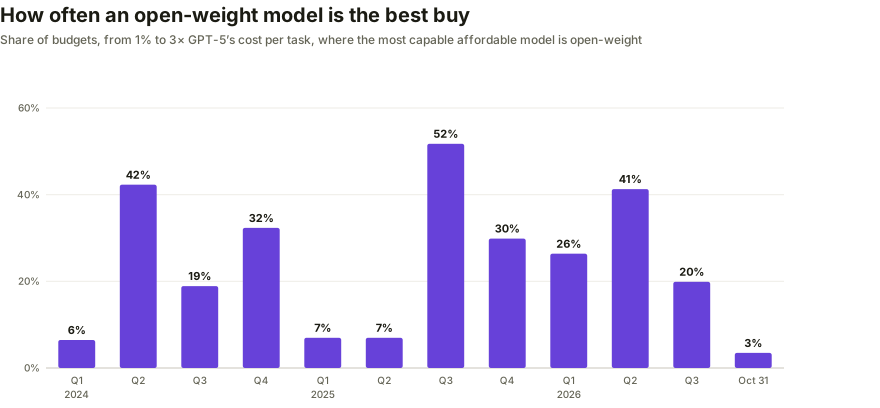
- Today’s share is the lowest we have measured. At the end of every quarter since 2024, open models held at least 6% of budgets.
- The peaks came from single releases. DeepSeek-V3.2-Exp was the best buy at nearly half of all budgets the week it launched in September 2025.
- None of them lasted. After each peak, the open share fell by about half or more by the next quarter as closed labs shipped cheaper tiers.
Open models win on value in bursts: a strong, cheap release, usually from DeepSeek, takes a wide band of budgets until the next closed model undercuts it. The latest closed releases have been both cheaper and stronger than anything open, so the band has shrunk to the very bottom of the price range.
Why closed labs may be winning on value
Three explanations fit the pattern:
- Closed labs can distill their own frontier models. A lab with the strongest model can train cheaper ones on its outputs in-house, and today’s cheap closed tiers followed their flagships within weeks, as Claude Haiku 5.5 did two weeks after Claude Opus 5.5. Open labs have to start from their own, weaker models, since closed labs’ terms generally bar training competitors on their outputs.
- Closed labs release whole families. OpenAI’s GPT-6 and GPT-6.1 models, from Luna and Terra up to Sol and Astra, hold 11 of the frontier’s 21 points between them, so one generation covers nearly every price.
- Closed labs may serve more cheaply. OpenAI, Anthropic and Google run inference at enormous scale, Google on its own chips, which can lower what each task costs; most open-model labs serve far less traffic.
How we built this
This study uses Village’s LLM Atlas, which estimates a capability score for each model and reasoning setting from public benchmark results and, with a separate cost model, its cost per task from evaluators’ runs, described in its methodology. Costs are relative to GPT-5 at high effort. For each date, we take every model released by then and find the most capable one at each of 201 budgets spread evenly on a log scale from 1% to three times GPT-5’s cost. The scores are from October 31, 2026; Atlas updates as new results arrive.
Costs reflect what evaluators paid through hosted APIs, and open models can be cheaper to run on your own hardware. Restricting to models scored on at least 10 benchmark families, or narrowing the budgets to 3% to one times GPT-5’s cost, gives the same pattern; widening them to 0.3% to ten times raises today’s share to 16%, because tiny open models still win at the very cheapest end.