In open-weight AI, America is the one playing catch-up
Open-weight AI models, whose weights anyone can download and run, have become China’s specialty. Labs like DeepSeek, Alibaba’s Qwen team, Zhipu and Moonshot release their strongest models openly, while most American labs keep theirs closed. Village’s LLM Atlas puts 857 models on one capability scale estimated from hundreds of public benchmarks, which lets us compare each country’s best open model day by day. By that measure, America’s open models have been behind for more than two years.
China has led every day since September 2024
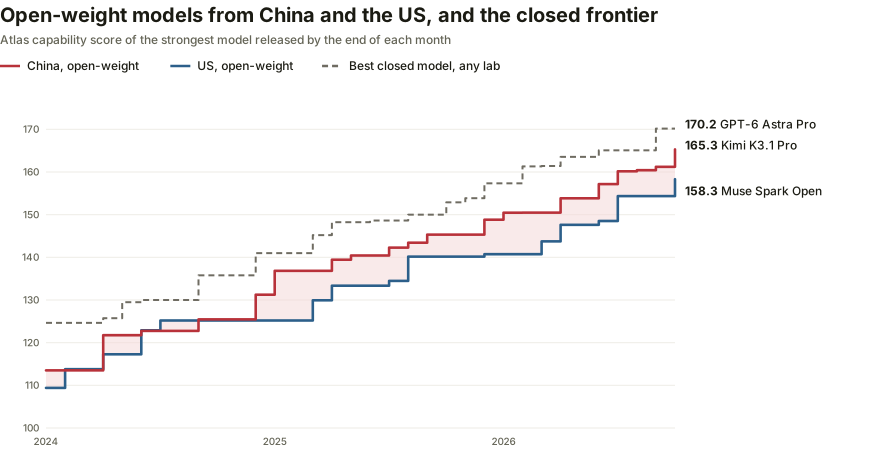
- The lead has held for more than two years. Meta’s Llama 3.1 405B last matched China’s best open model in September 2024, before Alibaba’s Qwen2.5 pulled ahead.
- It is typically about five months of progress. Since 2025, China’s lead has usually been 6 to 8 points; Atlas’s frontier climbs about 1.4 points a month.
- The latest push lasted two days. Meta’s Muse Spark Open cut the lead to 2.9 points on October 15; DeepSeek’s updated V4.1 Flash widened it two days later, and Moonshot’s Kimi K3.1 Pro took it to 7 points on October 24.
The pattern repeats: the gap narrows when Meta, OpenAI or Google ships an open model, then widens when DeepSeek, Zhipu or Moonshot answers.
America’s best open models arrive months late
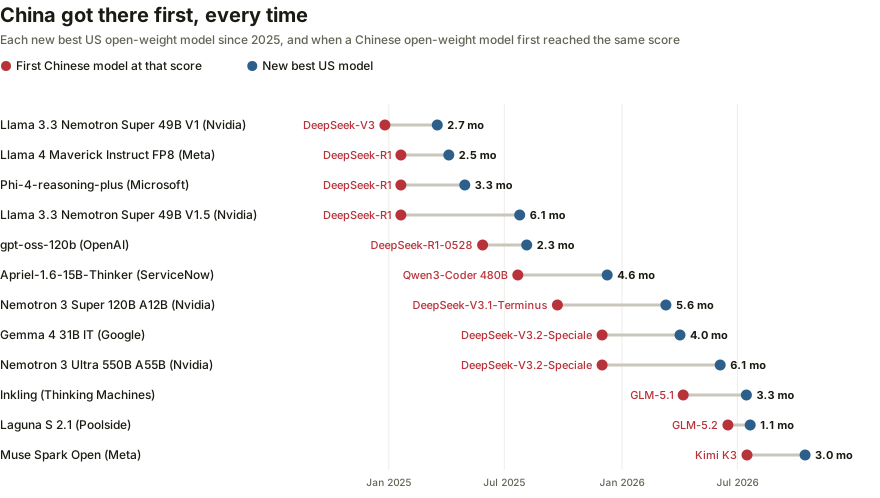
- Every new American record since 2025 came after China got there first. The 12 record-setting US open models arrived a median of 3.3 months after a Chinese open model reached the same score.
- Even the best showing was a month behind. Poolside’s Laguna S 2.1 came closest, at 1.1 months, in July.
More American labs are trying. Meta, Poolside and Thinking Machines have each released an open model within about three months of China’s best since July, after none did in the first half of the year. So far that has narrowed the gap without closing it.
Both still trail closed models
Neither country’s open models have caught the best closed ones. Since 2024, China’s best open models have typically trailed them by about five months, and America’s by about nine.
How we built this
This study uses Village’s LLM Atlas, which estimates one capability score per model from public benchmark results with a Bayesian item-response model, described in its methodology. For each day, we take the highest score among open-weight models each country’s labs had released by then, assigning labs to the country of their headquarters. Months behind measures how long before a model’s release a Chinese open-weight model first reached the same score. The scores are from October 31, 2026; Atlas updates as new results arrive.
Moonshot released Kimi K3.1 Pro on October 24 without weights. It is a post-trained version of Kimi K3, which Moonshot released openly, so we count it as open-weight on the assumption that its weights follow; counted as closed, China’s current lead would be 4.1 points instead of 7. Restricting to models scored on at least 10 benchmark families gives the same start date for China’s lead and similar gaps. Thirty scored models have no confirmed release date and are left out; none is an American model strong enough to have set its country’s frontier, so including them could only widen China’s lead.